Private AI Readiness Checklist: 12 Questions Before You Buy
A private AI server can stall for lack of an answer as easily as for lack of a GPU. Twelve questions on data, people, room and money show whether a business is ready to buy or should wait.
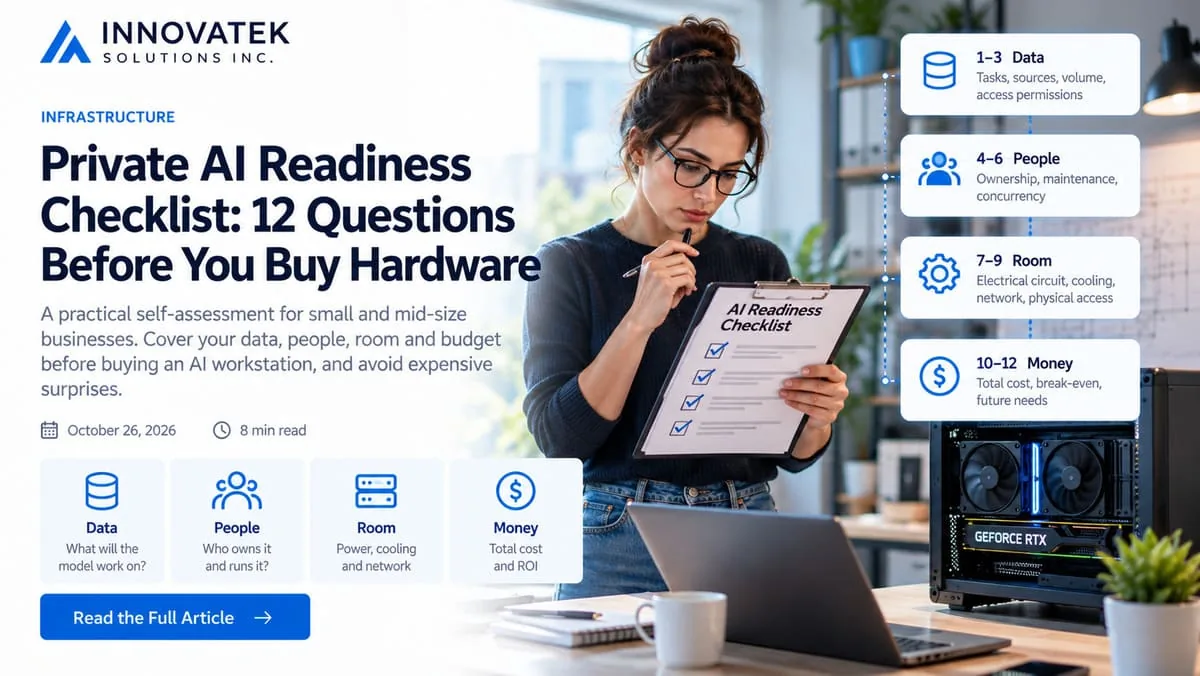
A workstation built around a 575 W graphics card can pull close to 900 W under load, and on a 15 amp circuit shared with a laser printer, it can trip the breaker the first afternoon it runs a long batch. This private AI readiness checklist is twelve questions, grouped as data, people, room and money, to answer before buying any hardware. Each one comes with what a good answer looks like, so a business can score itself honestly. It is a self-assessment, not an installation guide.
Data: what the model will actually work on
1. Which single task comes first, and can you show 20 real examples of it?
"Use AI across the company" is not a task. "Answer staff questions about our 400 policy documents" is. "Sort incoming supplier invoices into 12 cost codes" is.
A good answer names one task and has a folder of 20 or more real inputs, with the output a competent person would have produced for each. They become the test set that decides whether any model is good enough.
2. Where does that data live, and who is allowed to see it?
Private AI is usually justified by sensitive data, so that data has to be located and classified first. Each source has its own export path and its own permissions.
A good answer lists the systems the task reads from, says how the text gets out of them (export, API, file share), and states whether everyone using the tool may see every document. If permissions differ by person or client, that shapes the whole design.
3. How much text goes through it on a busy day?
Volume decides hardware size far more than headcount does. Count it in documents and in rough tokens, where a token is a word fragment and an English page is commonly a few hundred tokens.
Take a 20-person firm that expects 300 document questions a day. If each question sends about 3,000 tokens of retrieved text and gets back about 300 tokens of answer, that is 300 x 3,300 = 990,000 tokens a day, or about 21 million over a 21-day working month. A good answer is a figure like that, with the assumptions written next to it, because it feeds straight into the cost comparison in the break-even between a local LLM and a cloud API.
People: who owns it and who keeps it running
4. Who owns the outcome?
Someone on the business side has to decide when the tool is good enough to rely on, and when to switch it off.
A good answer is a named person with authority over the workflow being changed, plus the success measure they have agreed to, for example "85 percent of answers on the test set rated correct by the office manager, with a citation to the source document".
5. Who will patch, back up and restart it, and for how many hours a month?
A local AI server is a server. The operating system, graphics driver and inference software need updates that sometimes conflict, the model disk fills up, and the service occasionally stops at 9 a.m. on a Monday.
A good answer names an administrator or outside provider, a monthly hour budget, and who covers during leave. "The IT person will figure it out" is not an answer.
6. How many people will use it at the same moment?
Headcount and concurrency are different numbers. Forty staff who each ask five questions a day generate 200 questions, but if most arrive between 9 and 11 a.m., the peak might be four or five requests running at once. A single card that feels fast for one user can queue badly under that load.
A good answer estimates peak simultaneous requests from real working patterns, not from the staff list. The method for turning that estimate into hardware is in how many users one GPU can serve.
Room: where the machine will physically sit
7. Which electrical circuit will it use, and what else is on it?
Power is the most common surprise. NVIDIA lists the GeForce RTX 5090 at 575 W of total graphics power and 1000 W of required system power on its product page as of October 2026.
Work it through for a machine that draws about 900 W under sustained load on a 120 V circuit:
- Current: 900 W / 120 V = 7.5 A.
- The National Electrical Code treats a load running three hours or more as continuous and sizes the breaker at 125 percent of it, as explained by IAEI Magazine on NEC 210.19 and 210.20. So 7.5 A x 1.25 = 9.4 A of breaker capacity.
- A 15 A breaker therefore has about 5.6 A left for everything else on that circuit, and less if the other loads also run for hours.
A good answer names the circuit, lists what else shares it, and has been checked by an electrician if the numbers are close. Overnight batch jobs are exactly the kind of load that counts as continuous.
8. Where does the heat go, and who will hear the fans?
At 3.412 BTU per hour per watt, 900 W is about 3,070 BTU per hour, roughly what a portable space heater gives off on its low setting. In an unventilated closet, the card throttles or shuts off. Under load, the fans are also loud.
A good answer identifies the spot, confirms air can move in and out (a vented door, an exhaust fan, or space in an existing server room with cooling), and keeps the machine away from desks.
9. How will the machine connect, and who can touch it?
The server needs a wired network connection, a way for staff to reach it, a way for the administrator to manage it remotely, and somewhere to send backups. A box under a reception desk holding indexed client files is a data store and needs treating like one.
A good answer covers the network placement (ordinary office network, a separate segment, or fully isolated), how users sign in, where backups go, and whether the room or rack locks.
Money: what it costs to own and to stop
10. What is the three-year budget, past the hardware invoice?
The card is the visible cost. Around it sit the rest of the machine, power, admin time, spares, software support and a refresh before the hardware is obsolete for the job.
For readiness, the test is less the size of the number than whether three things are written down:
- Every line has a figure or a quote, including the ones with no invoice, such as admin hours at a loaded hourly rate and setup labor.
- The budget says which pot pays. Hardware is usually a one-time capital purchase, while support, power and admin time recur every year, and they often sit with different budget owners.
- Someone with spending authority has seen the three-year total, not only the purchase price.
A good answer is a full three-year figure built the way the total cost of owning an on-premise AI server lays it out, signed off by the person who will be asked to renew it in year two. A GPU quote on its own is not an answer.
11. What does it replace, and how will the saving or gain be measured?
Every private AI purchase should displace something: hours of manual sorting, a cloud subscription, a backlog that costs clients, or a risk the business cannot accept from an outside service.
A good answer states the current cost of doing the task (for example, 2 staff hours a day on invoice coding at a known hourly rate) and the measurement that will show the change after rollout. Risk reduction is a fair answer too, if the risk is named specifically.
12. What happens if it does not work?
The safest purchase has an exit planned: a trial on a narrow task, a decision date, a fallback process for staff, and a view on what the hardware is worth if the project stops.
A good answer sets a decision date and the measure that will be used on that date. The structure for a short, measured trial is in how to run a 30-day private AI pilot.
Reading your answers
Not every gap carries the same weight. The four groups fail in different ways:
| Group | If unanswered | Fix before buying? |
|---|---|---|
| Data (1-3) | No way to test quality or size hardware | Yes, always |
| People (4-6) | Tool works in the demo, decays in use | Yes for 4 and 5; 6 can be estimated |
| Room (7-9) | Tripped breakers, overheating, exposed data | Yes, these are cheap to settle |
| Money (10-12) | Project cannot be judged a success or failure | Yes for 12; 10 and 11 can be refined |
A practical decision rule: if questions 1, 2, 4, 5 and 12 have written answers, the business is ready for a pilot on borrowed or modest hardware. If any of those five are blank, buying a server now mostly buys a machine that will wait for the answers. The remaining seven can be tightened during the pilot, using real usage numbers instead of guesses.
Frequently asked questions
Can a business with no IT staff still run private AI?
Yes, if question 5 is answered by an outside provider under a written arrangement that covers updates, backups and response times. Assuming one enthusiastic employee will absorb the job indefinitely does not work.
Is a laptop or desktop already in the office good enough to test with?
Often it is, for the data and people questions. A recent machine can run a small open model well enough to check whether the task is suitable and whether the test set is any good, which answers more of this checklist than any spec sheet. It will not tell you much about speed under a real office load.
Does the checklist change for a fully air-gapped installation?
The twelve questions stay the same, but questions 2, 5 and 9 get harder. Moving data in, applying updates and copying model files all need a controlled manual process, so the admin hour budget is higher and the network answer is fixed in advance.
How long does it take to answer all twelve questions?
For a single, well-defined task, most of the work is collecting the 20 examples and the volume figures, which is days of part-time effort rather than weeks, plus an electrician's visit if the power numbers are tight. If it drags on, question 1 is probably too broad.
Ready to Modernize Your Business?
Get your AI automation roadmap in minutes, not months.
Analyze Your Workflows →