Text-to-SQL: Asking Your Database Questions in Plain English
A local model can write SQL from a plain question if it sees the schema. The hard parts are keeping it read-only, checking the query before it runs, and catching answers that look right but are not.
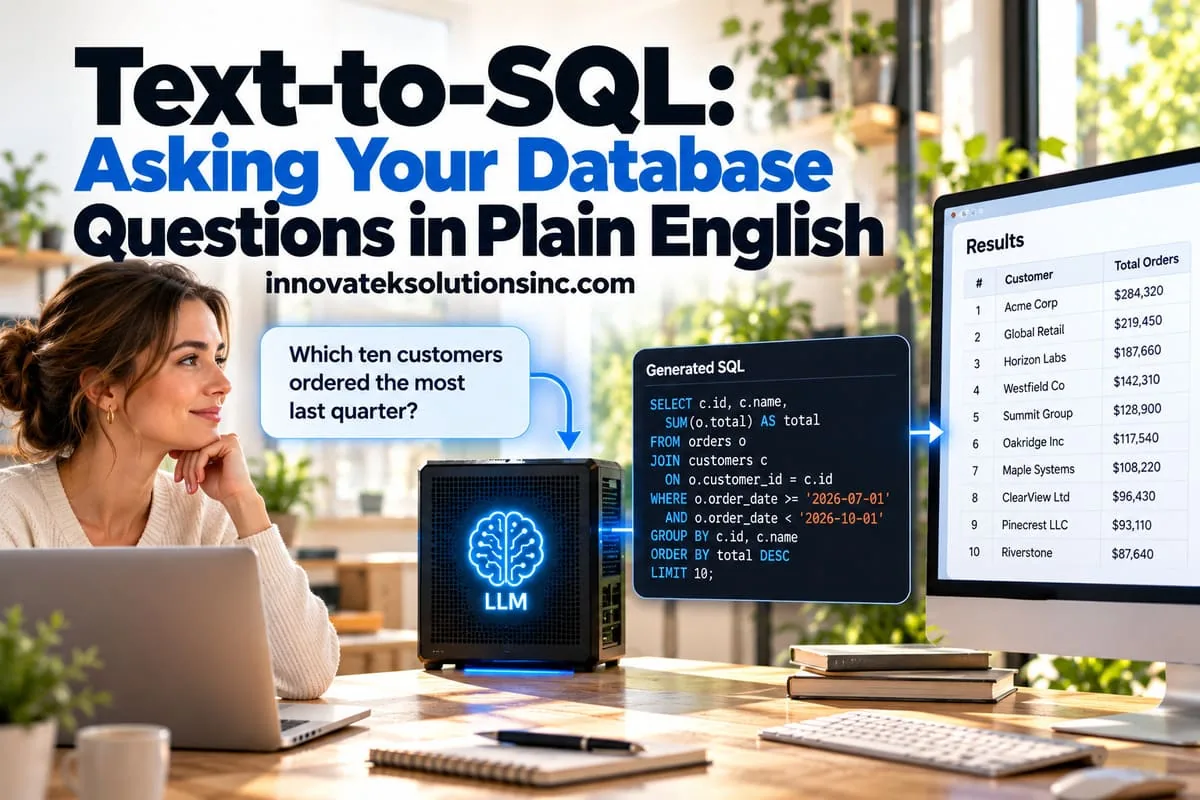
A sales manager types "Which ten customers ordered the most last quarter?" and gets back a table. Between the question and the table, a language model read a description of the database, wrote a SELECT statement, and a program ran it. That is text-to-SQL, and a local LLM on a company server can do it without sending the schema, the question or the result rows to an outside provider. Usefulness depends on what it is told about the database, what account the query runs under, what gets checked before execution, and whether the person asking can tell a right answer from a plausible wrong one.
How text-to-SQL works with a local model
The flow has five steps, and only one of them involves the model:
- The application collects the question and a description of the relevant tables.
- It sends both to the local model with an instruction to return one SQL query.
- Code parses and checks the returned query.
- The query runs against the database under a restricted account.
- The rows come back to the user, together with the SQL that produced them.
The model never touches the database directly. It produces text, and ordinary code decides whether that text gets executed. That boundary is the most important design choice in the system. If the application later lets the model request queries mid-conversation, the mechanics of function calling with local models apply, but the same check-then-run gate stays in front of the database.
Giving the model the schema
A model cannot write a correct query against tables it has never seen. The prompt has to carry table names, column names, types, and the relationships between tables. A compact format works better than a raw database dump:
orders(id int PK, customer_id int FK -> customers.id, order_date date, status text, total numeric)
order_lines(id int PK, order_id int FK -> orders.id, product_id int, qty int, line_amount numeric)
customers(id int PK, name text, region text)
Three things improve results more than switching models.
Comments on columns. A column called status with no further detail invites guessing. Adding the allowed values (status: 'open', 'shipped', 'cancelled') stops the model from filtering on 'complete', which does not exist and returns zero rows without any error.
A few example rows or example queries. Two or three known-good question and SQL pairs show the model your naming habits, date formats and which joins are normal.
Only the tables that matter. The schema text costs context. As a rough illustration, a database with 40 tables averaging 12 columns has 480 column lines. At around 10 tokens per line, that is about 4,800 tokens before the question is even asked, and real descriptions with comments run longer. Some local model servers start with a short default context window, so a large schema can be silently truncated. The usual fix is a first step that picks the relevant tables, either by keyword match against table and column descriptions or by embedding search, and passes only those five or six tables to the SQL-writing step.
Asking the model for structured output, for example a JSON object with a sql field and a tables_used field, makes the next step easier to automate. Techniques for getting reliable JSON out of a local LLM apply directly here.
A read-only database user is the first control
Whatever the model writes, it should run under an account that physically cannot change data. This control lives in the database, so it holds even if every other check fails.
In PostgreSQL, the clean approach is a dedicated login role granted SELECT on a specific set of tables or, better, views built for reporting. Views hide columns the tool should never read, such as bank details or personal notes, and pre-join awkward tables into shapes the model handles well.
Two PostgreSQL shortcuts look tempting and need care:
- The predefined role
pg_read_all_datagrants read access to all tables, views and sequences, plus usage on every schema, according to the PostgreSQL documentation. That is far broader than a reporting tool needs, and it would expose every sensitive table. - The setting
default_transaction_read_onlymakes new transactions read-only by default, as described in the client configuration docs. It is a default, not a permission, so a session can switch it back off. Grants are what actually stop writes.
Resource limits belong at the same layer. PostgreSQL's statement_timeout aborts any statement that runs longer than the set time, and ALTER ROLE ... SET statement_timeout makes it the session default for the reporting role. A session can still change it, so the validator should reject SET commands. MySQL has a comparable server-side limit, max_execution_time, set in milliseconds and applied only to top-level read-only SELECT statements. The MySQL team calls it a "soft hint" in its announcement of the feature, because the query may be interrupted slightly after the limit passes. A timeout of a few seconds stops an accidental cross join from tying up the server.
Validating the query before it runs
The read-only account stops damage; validation catches mistakes early. Parse the returned SQL with a real parser instead of regular expressions. SQLGlot, an MIT-licensed Python library that parses many SQL dialects into a syntax tree, is one option. With the tree in hand, code can check:
- Exactly one statement. Reject anything with a semicolon followed by a second statement.
- Statement type. Only
SELECT(andWITH ... SELECT). NoINSERT,UPDATE,DELETE,DROP,COPYorGRANT. - Allowed tables. Every table referenced must be on the list of views the tool is meant to use.
- A row limit. Add
LIMIT 1000if the query has none, so a missingWHEREclause does not pull a million rows into the chat window. - Cost. Running
EXPLAINfirst and rejecting queries whose estimated cost exceeds a threshold catches runaway joins before they start.
When validation fails, the error goes back to the model once with a short explanation ("table payroll is not available"), and it gets one retry. Endless retries hide a question the system cannot answer.
Free text stored in the database becomes a prompt injection route if the tool ever feeds result rows back into a prompt, for example to summarize them. A customer note can carry instructions that the database treats as a string and the model treats as orders. The read-only grants and table allowlist are what keep that from mattering.
Show the SQL to the user
Every answer should display the query that produced it. That is the only way to see what the model assumed.
Take the question "What was revenue in Q3?" The model might write:
SELECT SUM(total) FROM orders
WHERE order_date BETWEEN '2026-07-01' AND '2026-09-30';
A person reading this can spot three assumptions in seconds: Q3 means the calendar quarter, not a fiscal one; cancelled orders are included; and revenue means order totals, not invoiced or paid amounts. None of those is visible in a single number on screen. A plain-language restatement next to the SQL ("Sum of order totals, all statuses, orders dated July 1 to September 30, 2026") helps readers who do not read SQL.
The questions it gets wrong
Text-to-SQL fails quietly. A broken query throws an error, which is fine. A valid query that answers a slightly different question returns a confident number, which is the real problem.
Joins that multiply rows
Using the schema above, suppose an order worth $100 has three order lines. A query that joins orders to order_lines to filter by product, then sums orders.total, counts that $100 once per line. The result is 3 x $100 = $300 for one order. Across a quarter, the total is inflated by the average number of lines per order, and nothing in the output looks wrong.
The defenses are a view that already aggregates lines per order, column comments telling the model which table holds money at which level, and test questions that cover exactly this case.
Ambiguous business terms
"Active customer," "revenue," "churn" and "last quarter" each have a meaning inside the company that the schema does not record. The model will pick a definition without saying so. Column comments help a little. The stronger fix is the next section.
The way to know how often these happen is a test set: 50 or so real questions with known-correct answers, scored before launch and after every model change, the same method used for evaluating a RAG system.
A semantic layer for the terms that matter
A semantic layer is a file of named, agreed definitions sitting between the model and the raw tables. Instead of letting the model write SUM(total) and guess at filters, the company defines once that revenue is the sum of line_amount on shipped orders by invoice date, and that active_customer means an order in the last 365 days. Dimensions like region or fiscal_quarter get the same treatment.
The model's job then shrinks. It picks a metric, dimensions and filters from a known list and returns them as structured output, and ordinary code turns that choice into SQL. The model can no longer invent a revenue formula, because the formula is not its to write. It can still pick the wrong metric, but that choice is visible and easy to correct.
The trade-off is upfront work: someone has to maintain the definitions, and questions outside them fall back to free-form SQL with a warning or get declined. A practical decision rule: start with free-form SQL against a few curated views, log every question for a month, and move the ten most-asked metrics into a semantic layer first.
Frequently asked questions
Does text-to-SQL need a large model?
Larger models handle complex joins and long schemas better, but a mid-sized local model can do well on a small curated set of views with good column comments. The honest answer comes from running your own test questions against two or three model sizes and comparing accuracy against response time on your hardware.
Can the model write to the database if the user asks it to?
It can produce an UPDATE statement as text, but that text should never run. The parser rejects anything that is not a SELECT, and the database account has no write grants, so even a query that slips past the parser fails at the database.
Is it safe to let the model see real rows from the database?
Schema and a few sample rows help accuracy, but sample rows can carry personal data into prompts and logs. Use made-up sample values in the prompt, and check where prompts and results are logged, since a result table may hold more sensitive data than the question did.
How is this different from a dashboard?
A dashboard answers questions someone anticipated, with definitions already checked. Text-to-SQL answers new questions on demand, with the risk that each new query carries an untested assumption. A sensible split is to use it for exploration, then turn questions that keep coming back into proper dashboard reports.
Ready to Modernize Your Business?
Get your AI automation roadmap in minutes, not months.
Analyze Your Workflows →