How Much VRAM Does an LLM Need?
The VRAM a language model needs comes down to weights plus KV cache plus overhead. Here is the formula, three worked examples and what happens when a model spills into system RAM.
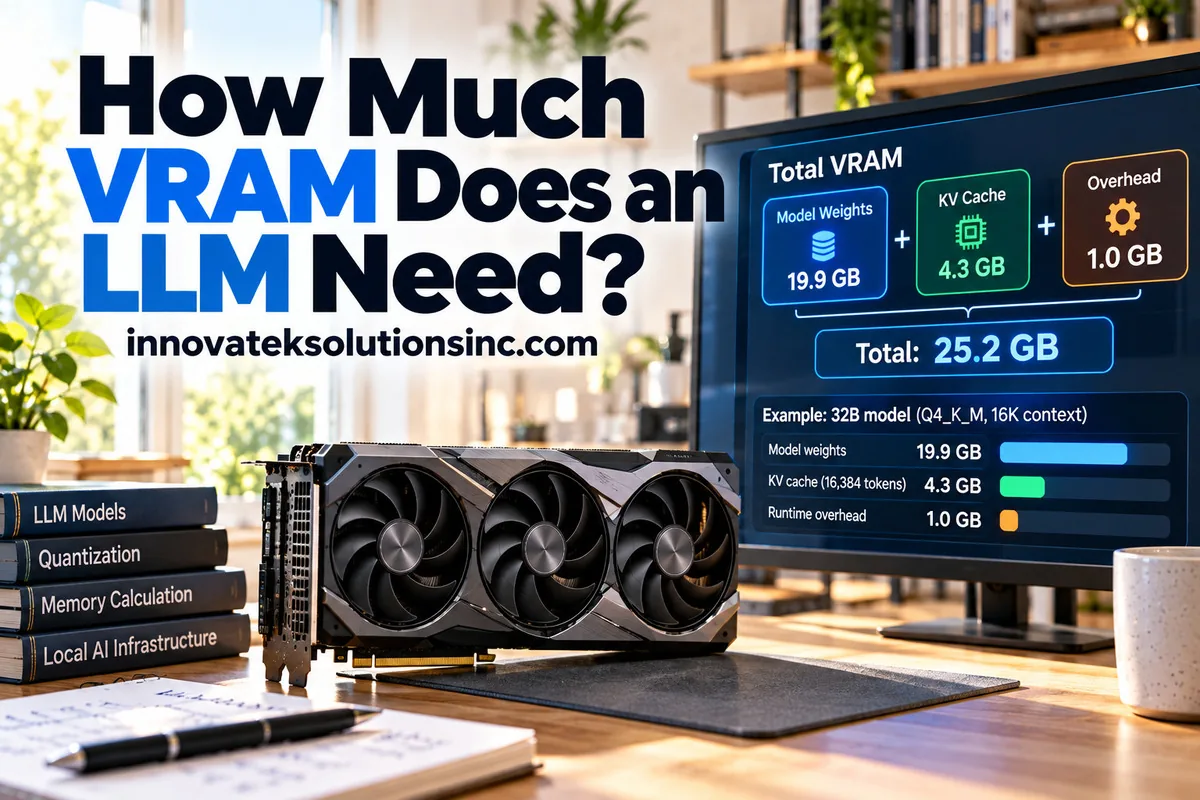
A 32-billion-parameter model stored at about 4.9 bits per weight takes 32.5 x 4.89 / 8 = 19.9 GB before it has read a single word of your prompt. Give it a 16,384-token context and it needs roughly another 4.3 GB to remember that context. Add the runtime's own working memory and a 24 GB card is already full. So the answer to how much VRAM an LLM needs is a sum of three parts, and each part can be worked out with a calculator and the model's config file.
The formula
Total VRAM is approximately:
weights + KV cache + overhead
The weights are fixed once you pick a model and quantization level. The KV cache grows with every token of context and every simultaneous conversation. The overhead is the smallest and least predictable.
Weights: parameters times bits per weight
Every parameter is a number, and the file stores it at some precision. The memory needed is:
weights (GB) = parameters (billions) x bits per weight / 8
At 16-bit precision (FP16 or BF16) that is 2 bytes per parameter, so a 7.6-billion-parameter model needs about 15.2 GB. Quantized formats shrink this. The llama.cpp quantization README lists the effective bits per weight for its common formats, measured on an 8B model:
| Format | Bits per weight | Bytes per billion parameters |
|---|---|---|
| F16 | 16.0 | 2.00 GB |
| Q8_0 | 8.50 | 1.06 GB |
| Q6_K | 6.56 | 0.82 GB |
| Q5_K_M | 5.70 | 0.71 GB |
| Q4_K_M | 4.89 | 0.61 GB |
The figures come from the llama.cpp quantize documentation. "4-bit" is really closer to 5 bits because the format stores scaling factors too; using 4.0 instead of 4.89 underestimates a 70B model by almost 8 GB. What each level costs in answer quality is a separate question, covered in what 4-bit and 8-bit quantization trade away.
KV cache: the memory cost of context
While the model reads your prompt and writes its answer, it keeps a key vector and a value vector for every token, in every layer. That store is the KV cache. Its size per token is:
KV bytes per token = 2 x layers x KV heads x head dimension x bytes per element
The 2 counts keys and values. Layers and KV heads come straight from the model's config.json (num_hidden_layers and num_key_value_heads). Head dimension is usually hidden_size / num_attention_heads. Bytes per element is 2 at the default 16-bit cache precision.
Modern models use grouped-query attention, where several query heads share one KV head, so a model with 64 attention heads but 8 KV heads needs one eighth of the cache an older design would.
Then multiply by context:
KV cache = KV bytes per token x context length x concurrent sequences
That last factor matters for a shared server. Four people each holding an 8,000-token conversation need the same cache as one person with 32,000 tokens. How that plays out under real load is the subject of how many users one GPU can serve.
Overhead
The runtime needs scratch buffers, the GPU driver reserves memory for its own context, and a desktop session may hold some VRAM for the display. It varies by runtime and driver, so treat it as an allowance. The examples below use 1 GB as a placeholder and the last section explains how to measure the real number.
Three worked examples
All three use Qwen2.5 Instruct models because their parameter counts and configs are published openly on Hugging Face.
Example 1: a 7B model on a single desktop card
Qwen2.5-7B-Instruct has 7.61 billion parameters, 28 layers, 28 attention heads, 4 KV heads and a hidden size of 3,584, according to its model card and config.
- Head dimension: 3,584 / 28 = 128
- Weights at Q4_K_M: 7.61 x 4.89 / 8 = 4.65 GB
- KV per token: 2 x 28 x 4 x 128 x 2 bytes = 57,344 bytes, about 57 KB
- KV at 32,768 tokens: 57,344 x 32,768 = 1.88 GB
- Overhead allowance: 1 GB
Total: 4.65 + 1.88 + 1 = about 7.5 GB. That is tight on an 8 GB card and comfortable on 12 GB. In FP16 the weights alone would be 15.2 GB, which is why small cards run quantized files.
Example 2: a 32B model that almost fits 24 GB
Qwen2.5-32B-Instruct has 32.5 billion parameters, 64 layers, 40 attention heads, 8 KV heads and a hidden size of 5,120.
- Head dimension: 5,120 / 40 = 128
- Weights at Q4_K_M: 32.5 x 4.89 / 8 = 19.87 GB
- KV per token: 2 x 64 x 8 x 128 x 2 bytes = 262,144 bytes, about 262 KB
- KV at 16,384 tokens: 262,144 x 16,384 = 4.29 GB
- Overhead allowance: 1 GB
Total: 19.87 + 4.29 + 1 = 25.2 GB. It does not fit a 24 GB card. There are three levers, and each has a cost:
- Shorter context. At 8,192 tokens the cache halves to 2.15 GB and the total drops to 23.0 GB. Long documents then get cut off, a problem explained in why long documents break local LLMs.
- Quantized KV cache. llama.cpp exposes
--cache-type-kand--cache-type-vwithq8_0among the options, and Ollama'sOLLAMA_KV_CACHE_TYPE=q8_0does the same. The Ollama FAQ describesq8_0as about half the memory off16with a very small loss in precision, and notes it applies when Flash Attention is enabled. Becauseq8_0stores about 8.5 bits per value against 16, the 16K cache shrinks to 4.29 x 8.5 / 16 = 2.28 GB and the total to 23.2 GB. - A smaller weight format. Saves a few gigabytes, usually at a higher quality cost than the first two.
Combining the first two, 8K context with a q8_0 cache, gives 19.87 + 1.14 + 1 = 22.0 GB and leaves real headroom.
Example 3: a 72B model for a small team
Qwen2.5-72B-Instruct has 72.7 billion parameters, 80 layers, 64 attention heads, 8 KV heads and a hidden size of 8,192.
- Head dimension: 8,192 / 64 = 128
- Weights at FP16: 72.7 x 2 = 145.4 GB
- Weights at Q4_K_M: 72.7 x 4.89 / 8 = 44.44 GB
- KV per token: 2 x 80 x 8 x 128 x 2 bytes = 327,680 bytes, about 328 KB
- KV for 4 users at 8,192 tokens each: 327,680 x 32,768 = 10.74 GB
- Overhead allowance: 1 GB, more if the model is split across cards
Total at Q4_K_M: 44.44 + 10.74 + 1 = about 56 GB. The cache is now nearly a fifth of the budget, and every additional concurrent user adds 2.7 GB. That is more than a 48 GB card holds, so on that class of hardware it means two GPUs, a quantized cache, fewer simultaneous sessions, or a smaller model.
When the model spills into system RAM
If the total exceeds VRAM, most local runtimes do not refuse to load. They put part of the model in ordinary system memory. llama.cpp controls this with --n-gpu-layers, which sets how many layers live in VRAM (default auto); the rest run on the CPU. Ollama decides automatically, and ollama ps shows the split in its Processor column, for example 48%/52% CPU/GPU. Anything other than 100% GPU means part of the model is in system RAM.
It still answers, slowly. Generating each token requires reading every weight once, so speed is limited by memory bandwidth. Take an illustrative card with 1,000 GB/s of VRAM bandwidth and a desktop with dual-channel DDR5-5600, which works out to 5,600 million transfers x 8 bytes x 2 channels = 89.6 GB/s.
- All 20 GB of weights in VRAM: 20 / 1,000 = 20 ms per token, a ceiling of 50 tokens per second.
- 15 GB in VRAM and 5 GB in system RAM: 15 / 1,000 + 5 / 89.6 = 15 ms + 56 ms = 71 ms per token, a ceiling of about 14 tokens per second.
Moving a quarter of the model off the card cut the theoretical speed by more than two thirds. Real throughput sits below both ceilings, and a model that spills by a few gigabytes usually performs worse than a smaller model that fits.
Mixture-of-experts models are a partial exception: memory follows the total parameter count, but each token reads only the active experts, so a spilled MoE model degrades less than a dense one.
Checking the estimate against reality
The formula gets within a few gigabytes. Load the model with the exact context length and parallel-request setting you plan to use in production, run a prompt that fills that context, and read actual usage with nvidia-smi or ollama ps. Two settings catch people out. Ollama's default context is 4,096 tokens per the FAQ, so a model that seemed to fit may spill when the context is raised to what real documents need. And llama.cpp's --ctx-size defaults to the value stored in the model file, which can be far larger than you intended.
A workable decision rule: compute weights plus KV cache for your real context and concurrency, add 10 to 15 percent, and require the result to fit entirely in VRAM. If it does not, change the context, the cache precision or the model before considering a bigger card, and when a bigger card is the answer, how to choose a GPU for a local LLM covers what to compare after capacity.
Frequently asked questions
Where are the layer and head counts for a model listed?
Open the model's config.json on Hugging Face and look for num_hidden_layers, num_attention_heads, num_key_value_heads and hidden_size. GGUF files carry the same values in their metadata, and llama.cpp prints them when it loads a model. Some newer architectures set head_dim explicitly, in which case use that instead of dividing.
Does a GGUF file's size on disk equal the VRAM it needs?
It approximates the weights term only, since the file holds the quantized weights plus a little metadata. The KV cache and overhead come on top and depend on how the model is run, not on the file.
Why does the same model use more VRAM in one tool than another?
Runtimes pick different default context lengths, parallel slot counts and cache precisions, and each multiplies the KV cache. A server reserving cache for four long sequences can use several times the memory of a desktop app holding one short chat.
Is GB or GiB the right unit for these numbers?
The formulas above give decimal gigabytes, while tools such as nvidia-smi report in mebibytes and some documentation uses GiB. One GiB is about 7 percent larger than one GB, so a 24 GB figure on a spec sheet and 22.35 GiB in a tool can be the same memory. Convert before deciding whether something fits.
Ready to Modernize Your Business?
Get your AI automation roadmap in minutes, not months.
Analyze Your Workflows →